Article
The Pelican Test: How Chinese Developers Benchmark AI Models With a 3D Pelican
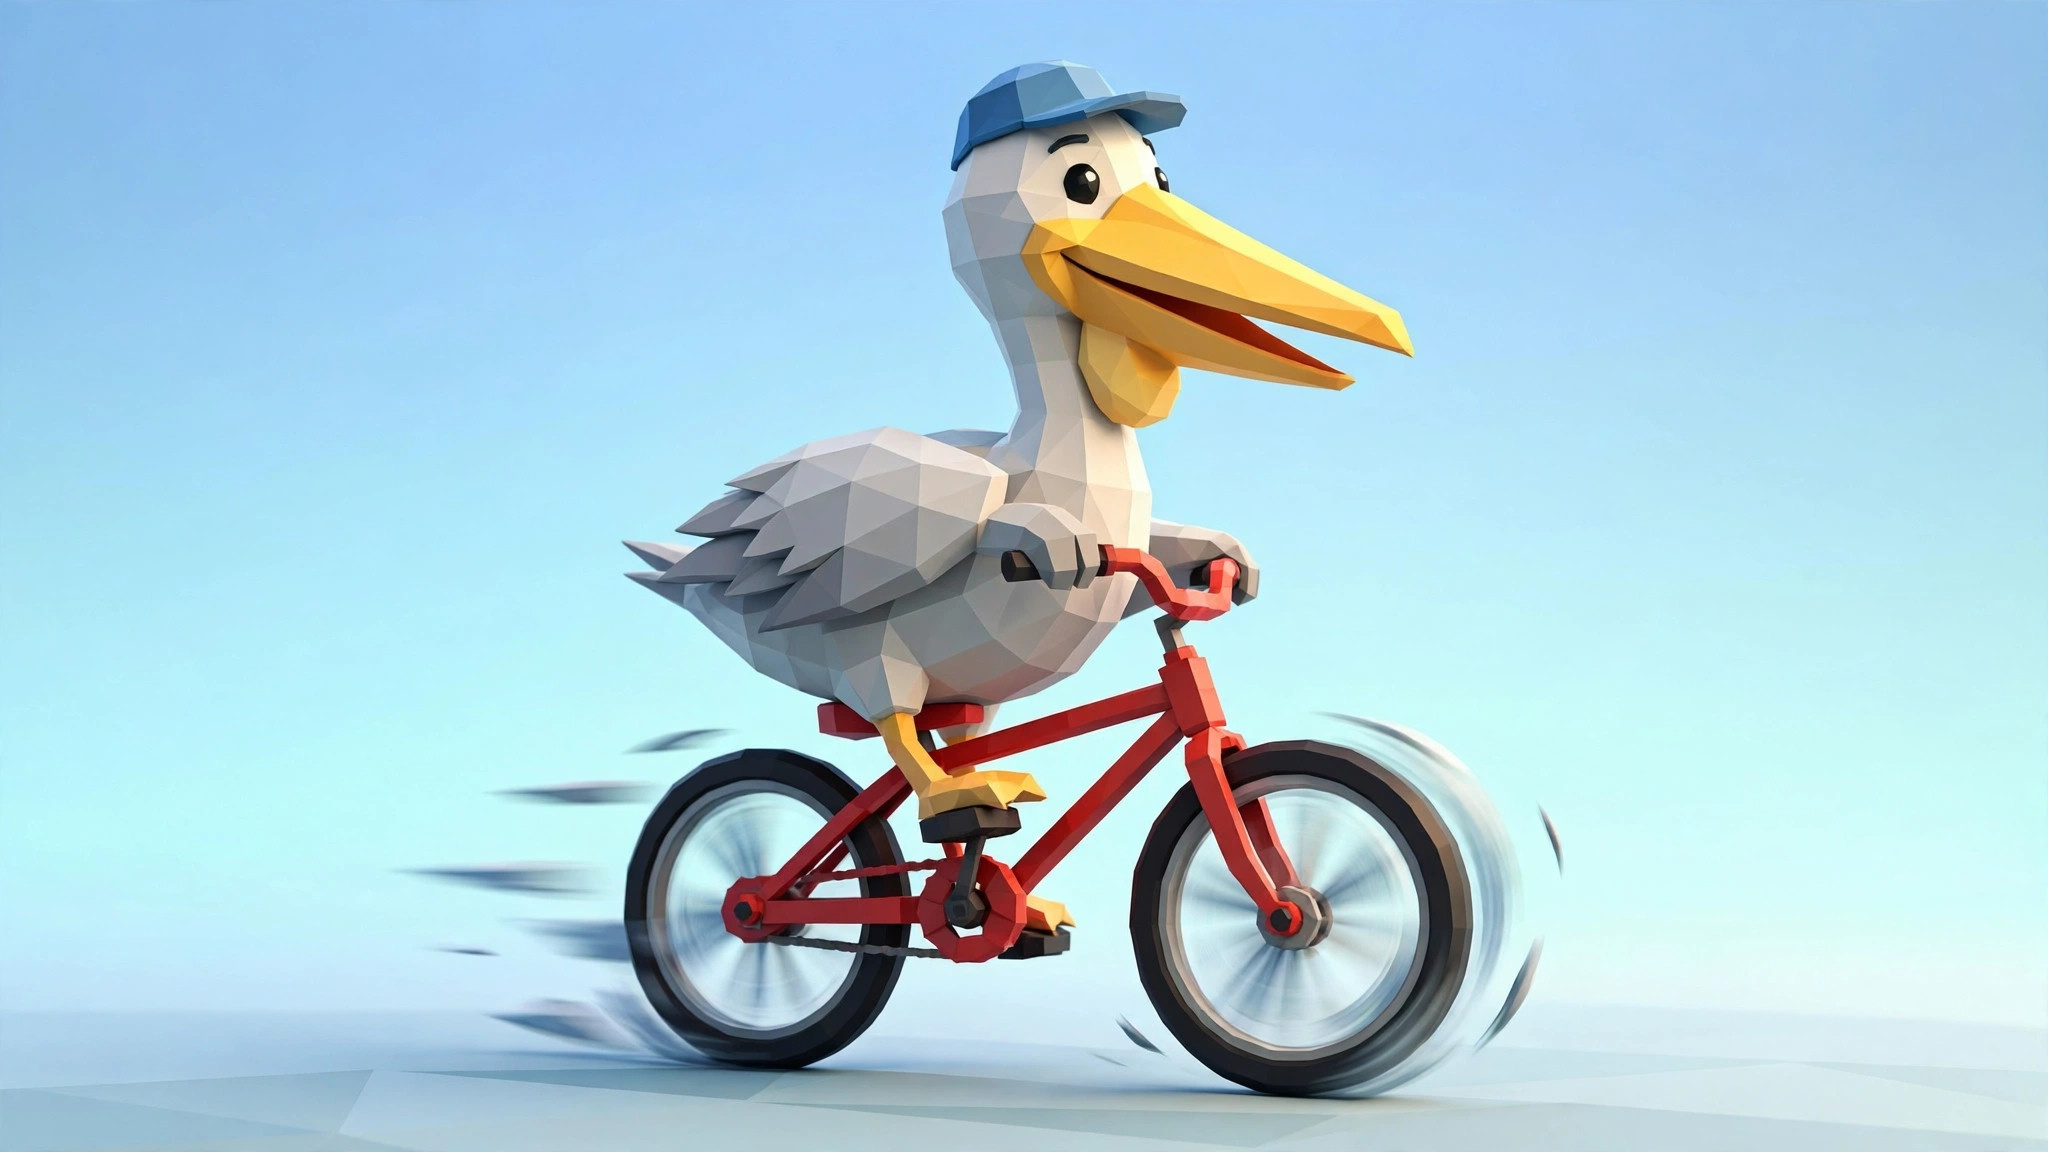
Forget MMLU and HumanEval. In China's developer community, one of the most beloved AI benchmarks involves a pelican riding a bicycle — rendered in 3D, generated from a single prompt.
The story starts with a thread on LINUX DO — one of China's largest developer forums — that exploded after a member shared demos generated by a then-rumored new model: a QQ Speed-style 3D racing game and a cargo ship demo, each reportedly produced from a single sentence of prompting and hosted on Cloudflare Pages. The thread pulled hundreds of replies and over 13,000 views in days, with the original post collecting hundreds of likes. (The rumored model was later confirmed: Anthropic released Claude Opus 5.5 on September 22, 2026, per TechCrunch's reporting. The community promptly nicknamed it "pelican" — 鹈鹕 — after their own test.)
But the detail that stuck wasn't the racing game. It was the community's homegrown evaluation ritual: the 3D pelican test. Ask a model to generate an interactive 3D pelican — preferably one riding a bicycle — and judge the model by what comes back. Different models get run through the same absurd prompt, and the results are compared side by side. "Pelican" has become the forum's unofficial unit of generative capability.
It sounds like a joke, but the pelican test is a surprisingly good evaluation. A single prompt exercises almost everything a code-generating model needs to be good at:
| What the test demands | What it reveals |
|---|---|
| 3D geometry (beak, wings, webbed feet) | Spatial reasoning and anatomical knowledge |
| A bicycle (frame, wheels, pedals) | Compositional complexity — two hard objects interacting |
| "Riding" (animation, balance) | Whether the model understands motion and physics |
| One-shot, no iteration | Raw capability, not the user's prompt-engineering skill |
| Visual output | Taste — proportions, colors, and polish you can see |
Standard benchmarks can be gamed or memorized. Nobody trains a model specifically to draw pelicans on bicycles, which makes it a delightfully honest test. A thread debating whether one viral demo was "real 3D rendering or just SVG" shows the community takes the methodology more seriously than the silliness suggests.
There's a deeper technical reason the test has teeth. Generating a working Three.js scene in one shot requires the model to hold a large, coherent plan: scene graph, camera, lighting, geometry, animation loop, and event handling — all in a single artifact. A model that can do that reliably is demonstrating long-horizon coherence, the same muscle that matters for real engineering tasks like scaffolding a project or writing a self-contained script. The pelican is funny; the capability it probes is not.
The pelican test belongs to a growing movement of vibes-based benchmarking — evaluating models the way users actually experience them, through open-ended creative tasks rather than multiple-choice exams. Western developers do the same thing when they ask a model to "build a landing page" or "clone Flappy Bird" and judge by feel. "Build me a snake game with a twist" has probably decided more real purchase decisions than any leaderboard.
What makes the Chinese version interesting is how it became shared infrastructure: a common prompt, a shared joke, and comparable results across models. When everyone runs the same pelican, you get something multiple-choice tests can't give you — a leaderboard with a sense of humor. And because the test is visual, the results are instantly legible: you don't need to understand the scoring methodology to see that one pelican has charm and another is a traffic accident.
The movement is also a quiet vote of no confidence in the benchmark-industrial complex. As model capabilities converged on saturated leaderboards — where the difference between top models is smaller than the measurement noise — practitioners started trusting their own eyes. The pelican test is the logical endpoint: a benchmark that is transparent (you can see the output), ungameable (nobody optimizes for pelicans), and calibrated to the only metric that ultimately matters (would you ship what this model made?).
For all its charm, the pelican test has real weaknesses, and the forum's sharper members have named them:
The right way to read pelican results is as a complement to formal benchmarks, not a replacement. MMLU tells you what a model knows; the pelican tells you what a model can do with what it knows, in a form a human can judge in ten seconds.
Want to try it? The recipe from the forums is simple:
One tip from the community: run the exact same prompt on two or three models back to back, before you look at anyone else's results. The side-by-side comparison is where the test earns its keep — the differences that are invisible in isolation become obvious when the pelicans race.
If you're curious how Chinese developers think about AI more broadly, it's worth knowing this is the same community currently dissecting why a game studio wants to build a top-tier LLM — the pelican is just the friendliest entry point into a community that evaluates AI the way it uses AI: relentlessly, practically, and with a sense of humor.
The pelican test's real legacy may not be the pelican at all. It's the proof that a community can build its own evaluation infrastructure — shared prompts, shared results, shared vocabulary — faster than any standards body. Formal benchmarks take months to design and years to saturate; a forum can mint a new one in an afternoon and retire it just as fast when it stops being informative. That agility is a feature, not a bug: evaluation that moves at the speed of the models it evaluates. Expect more pelicans — the next absurd animal is probably already being rendered somewhere.